Website Uptime Monitoring for Small Businesses: Why It Matters and How to Start
Learn how to monitor website availability, forms, checkout flows, SSL, DNS, and downtime before lost leads become lost revenue.
Aslisite Team
Digital Experts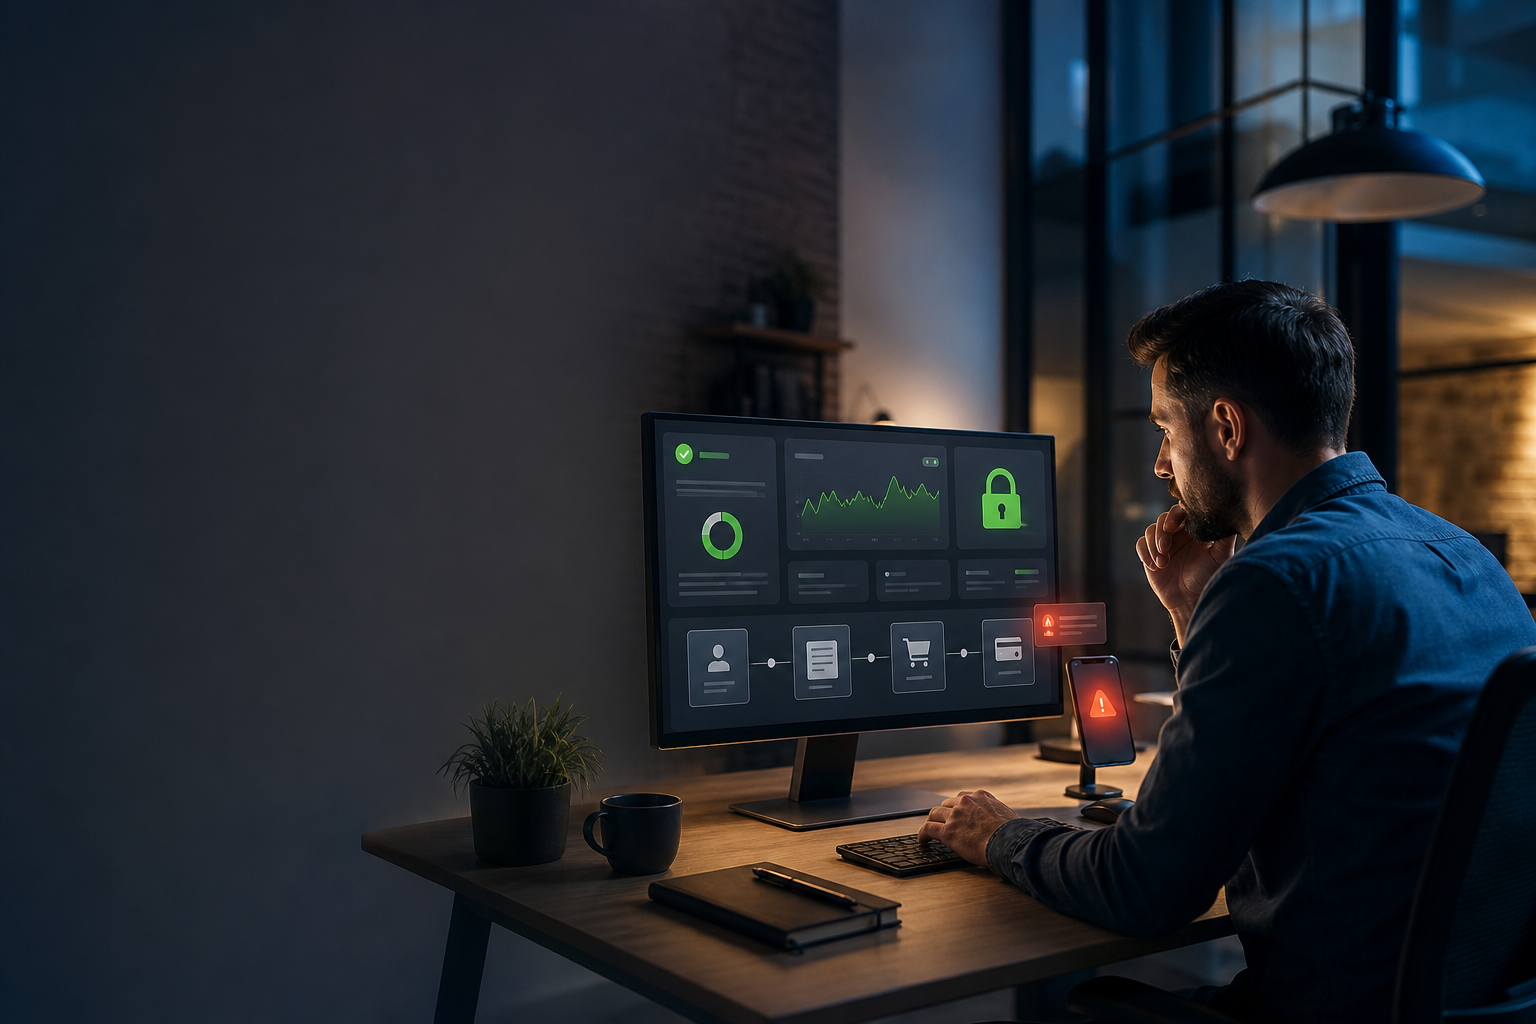
Table of Contents
What is uptime monitoring?
Uptime versus performance monitoring
What to monitor first
1. The homepage and key landing pages
2. Contact and lead forms
3. Booking and appointment flows
4. Product pages and checkout
5. Login areas and customer portals
6. APIs and third-party services
Forms, checkout, and API checks
SSL, DNS, and domain monitoring
SSL certificate monitoring
DNS monitoring
Domain expiry monitoring
Alerts and response times
Incident-response checklist
How to choose a monitoring tool
When managed monitoring is worthwhile
If your website generates leads, bookings, sales, support requests, or phone calls, downtime is a business problem—not just a technical inconvenience. A few minutes of failure can mean missed enquiries, abandoned checkouts, frustrated customers, and a team that discovers the issue through social media instead of an alert.
Website uptime monitoring for small businesses gives you an early warning when your site, critical page, form, checkout, API, SSL certificate, DNS, or domain registration stops working. The goal is not simply to collect a percentage such as 99.9% uptime. It is to detect problems quickly, identify what customers cannot do, and follow a repeatable response process.
This guide explains what to monitor, how uptime differs from performance monitoring, which alerts matter, and when managed monitoring is worth paying for.
What is uptime monitoring?
Uptime monitoring is the automated checking of a website or online service at regular intervals to confirm that it is reachable and behaving as expected. A basic HTTP monitor requests a URL and checks whether it returns a successful response. More useful monitors can also check response content, API results, DNS records, SSL certificates, domain expiry, and multi-step browser journeys.
Most uptime-monitoring services run checks from outside your hosting environment. This is important because a server dashboard may show that a server is running even when customers cannot resolve the domain, complete a form, or load the site through HTTPS.
For example, Better Stack describes uptime monitoring as an external synthetic check that alerts the responsible person when a service becomes unavailable. Its documentation also lists HTTP status, keyword, DNS, SSL and domain-expiration checks, along with browser-based Playwright scenarios.
Uptime is usually reported as a percentage over a period. However, a high percentage can hide a serious incident. A website that is unavailable for 40 minutes during a busy campaign may still show an acceptable monthly figure, while the commercial impact is substantial. For a small business, detection time, response time, and recovery time are often more useful measures than the headline uptime number alone.
Uptime versus performance monitoring
Uptime and performance monitoring answer different questions:
- Uptime monitoring: Can a customer reach the page or service, and does it return the expected result?
- Performance monitoring: How quickly does the page respond, render, and become usable?
- Transaction monitoring: Can a customer complete an important action, such as submitting a form or checking out?
A page can be technically available but still unusable. It may return a 200 status while loading slowly, displaying a broken layout, failing to load JavaScript, or showing an error message inside the page. Conversely, a speed test can report acceptable load times while a booking form or payment step is broken.
Synthetic monitoring is the practice of using automated requests or browser scripts to simulate user activity from a consistent environment. MDN explains synthetic monitoring as a controlled way to test page performance and user journeys. It is useful for repeatable checks, but it does not replace real-user data because it cannot represent every device, network, browser, or location.
For most small businesses, the practical approach is to use basic uptime checks for important pages, performance monitoring for speed trends, and transaction checks for revenue-generating actions.
What to monitor first
You do not need to monitor every URL on your website. Start with the pages and services that affect revenue, reputation, or customer communication.
1. The homepage and key landing pages
Monitor the homepage, campaign landing pages, service pages, location pages, and any page that receives paid or organic traffic. Check both the HTTP response and, where supported, an expected phrase or page element. A page that returns a successful status but displays a hosting error should still be treated as a failure.
2. Contact and lead forms
A form needs more than a page-load check. A useful test should confirm that the form loads, accepts valid input, submits successfully, and produces the expected confirmation. If possible, verify that the notification reaches the correct inbox or CRM without using real customer data.
Use a dedicated test address and a clear marker such as “monitoring test” so staff do not mistake automated submissions for genuine enquiries. Avoid sending sensitive personal information through monitoring scripts.
3. Booking and appointment flows
If customers book appointments, monitor the journey from the booking page through date selection, time selection, customer details, confirmation, and any calendar or email notification. A booking page that loads but cannot retrieve available slots is not functioning for customers.
4. Product pages and checkout
For ecommerce sites, monitor the product page, cart, checkout, payment hand-off, and confirmation page. A complete payment test may create accounting, refund, or fulfilment complications, so many businesses monitor the journey up to the payment provider or use a provider-supported test mode.
Monitor the payment provider separately when possible. A website can be available while a payment gateway, tax calculation service, shipping API, or inventory connection is failing.
5. Login areas and customer portals
If customers depend on a login, dashboard, member area, or support portal, test authentication and a safe read-only action. Do not store production passwords in a monitoring tool unless the security controls, access permissions, and vendor terms are appropriate for your business.
6. APIs and third-party services
Monitor APIs that power search, forms, product availability, booking slots, stock levels, or customer notifications. A basic API check can verify the status code. A deeper check can validate response time, required fields, or an expected value.
Forms, checkout, and API checks
These checks are often called transaction monitoring or browser-based synthetic monitoring. They simulate a sequence of actions rather than checking one URL. Depending on the tool, a scenario may run in a real browser and interact with buttons, fields, menus, and JavaScript-driven elements.
When designing a transaction check:
- Choose one business-critical journey rather than trying to automate the entire website.
- Use test accounts, test products, or sandbox payment credentials where available.
- Keep the steps stable and avoid unnecessary clicks that are likely to change.
- Set a useful failure condition, such as a missing confirmation message or unexpected API response.
- Record screenshots, error messages, and timestamps so the person responding can investigate quickly.
- Review the script after website releases, theme changes, plugin updates, and checkout changes.
Some tools combine uptime and transaction monitoring with incident-management features. Better Stack’s website-monitoring product page, for example, describes uptime checks for websites, APIs, DNS, SSL, and domain expiry alongside browser-based transaction checks for sign-up, login, and checkout flows. Features change over time, so confirm current limits, locations, integrations, and retention before choosing a provider.
SSL, DNS, and domain monitoring
Website availability depends on more than the web server.
SSL certificate monitoring
An expired or incorrectly configured SSL certificate can trigger browser warnings, block connections, or damage customer trust. Monitor certificate expiry and alert well before the renewal date. A 30-day warning may be adequate for an automated renewal process, but businesses that renew manually may prefer earlier reminders such as 60 or 90 days.
Also check the certificate chain, hostname coverage, and whether the certificate is being served correctly from the important domains and subdomains. SSL monitoring should complement, not replace, a broader website security plan for business owners.
DNS monitoring
DNS translates a domain name into the address a browser uses to find the website. Cloudflare’s DNS guide explains this resolution process and why DNS is essential to reaching a site.
Monitor important DNS records and nameserver availability, especially after changing hosting providers, email services, CDNs, or domain settings. A DNS mistake can make a website or business email appear offline even when the hosting account itself is healthy.
Domain expiry monitoring
A missed domain renewal can disconnect the website, email, and other services that rely on the domain. ICANN recommends keeping track of the expiration date, maintaining current contact details, and considering auto-renewal with up-to-date payment information.
Do not rely on one reminder email. Monitor the expiry date, confirm who controls the registrar account, and document the renewal owner inside the business.
Alerts and response times
An alert is useful only if it reaches someone who can act. Configure alerts according to business impact rather than sending every event to every employee.
- Critical: Homepage, checkout, booking, lead forms, customer login, or payment-related failures. Use phone, SMS, push, or an on-call escalation when the business operates outside office hours.
- High: Important service pages, APIs, or regional failures. Use email, chat, or an assigned technical contact.
- Medium: Slow response times, certificate warnings, DNS changes, and domain-expiry reminders. Route these to the website owner or agency.
- Low: Non-critical pages, reporting anomalies, or recurring warnings that need review but not immediate interruption.
To reduce false alarms, use confirmation periods or multi-location verification where available. A temporary network issue at one monitoring location should not automatically trigger an emergency response. At the same time, do not make checks so tolerant that a genuine outage is discovered late.
Set a simple service target for each critical journey. For example, a small business might aim to acknowledge a checkout alert within 15 minutes during trading hours and contact its hosting provider or developer within 30 minutes. These are operating targets, not universal standards; choose times that reflect your traffic, staffing, and revenue risk.
Incident-response checklist
When an alert arrives, avoid guessing. Use a short checklist that helps separate a false positive from a real customer-impacting incident.
- Confirm the alert: Open the page from a separate network or device and check whether the issue is reproducible.
- Identify the scope: Determine whether the problem affects the whole site, one page, one region, logged-in users, forms, checkout, or a third-party service.
- Check recent changes: Review deployments, plugin updates, DNS edits, hosting changes, certificate renewals, and payment-provider changes.
- Capture evidence: Save the alert time, URL, status code, screenshots, error messages, affected steps, and monitoring location.
- Contain the impact: Pause advertising, disable a broken checkout option, publish an alternative contact method, or show a clear maintenance message if appropriate.
- Escalate: Contact the person responsible for hosting, development, DNS, payments, or the relevant vendor. Include evidence instead of sending only “the site is down.”
- Communicate: Tell staff what is affected, what customers should do, and when the next update will be provided.
- Verify recovery: Test the original failed page or transaction, not just the homepage. Confirm that forms, emails, payment steps, and integrations work again.
- Document and improve: Record the cause, duration, customer impact, response time, fix, and preventive action.
This approach reflects the broader incident-response principle of preparation, detection, response, recovery, and improvement. NIST’s current incident-response guidance emphasises detecting incidents, responding and recovering effectively, and feeding lessons learned back into future improvements.
How to choose a monitoring tool
When comparing tools, look beyond the number of monitors included. Check whether the service supports:
- HTTP and HTTPS checks with expected status codes
- Keyword or content checks for pages that return a successful status while showing an error
- Multi-location monitoring and false-positive reduction
- Browser-based transaction checks for forms, booking, login, and checkout
- API response and JSON validation
- SSL certificate, DNS, and domain-expiry monitoring
- Email, SMS, phone, push, Slack, or Microsoft Teams alerts
- Escalation rules when the first responder does not acknowledge an incident
- Maintenance windows to prevent alerts during planned work
- Response-time charts, incident history, screenshots, logs, and downloadable reports
- Clear data handling, access controls, retention, and support arrangements
Start with a small monitoring set: homepage, lead form, booking or checkout flow, SSL certificate, domain expiry, and one important API or third-party dependency. Review the alerts after two weeks. Remove noisy checks, improve failure conditions, and add monitors only where they help someone make a decision.
When managed monitoring is worthwhile
Self-managed monitoring is often enough when the site is small, the owner can respond quickly, and the business operates mainly during predictable hours. Managed monitoring becomes more valuable when the website handles payments or bookings, the owner is not technical, incidents occur outside office hours, multiple vendors are involved, or downtime has a clear financial cost.
A managed service may provide 24/7 alert routing, browser transactions, incident escalation, historical reports, and an external person or team who can investigate. It does not eliminate the need for a website owner. You still need documented access, a clear escalation path, and someone who can approve changes.
Uptime monitoring works best as part of ongoing care. Pair it with regular updates, backups, security reviews, and planned testing. For broader guidance, see why website maintenance remains important after launch.
The right starting point is simple: monitor what customers need to do, alert the person who can fix it, and document what happens when something fails. That turns website downtime from a surprise into a manageable business process.
Ready to scale your digital presence?
Join businesses growing with Aslisite. Let's discuss your project today.